
Skip to content
View lyhisme's full-sized avatar

Block or report lyhisme

Block user

Prevent this user from interacting with your repositories and sending you notifications. Learn more about blocking users.

You must be logged in to block users.

Content in all repositories owned by your account will be closed.
Maximum 250 characters. Please don’t include any personal information such as legal names or email addresses. Markdown is supported. This note will only be visible to you.
Report abuse

Contact GitHub support about this user’s behavior. Learn more about reporting abuse.

Report abuse
lyhisme/README.md

Yunheng Li — Multimodal, Embodied and Physical AI

Homepage Google Scholar Hugging Face Email

Ph.D. Candidate @ Nankai University  ·  Qingyun Program Intern @ Tencent Hunyuan

I build multimodal foundation models that can perceive, reason about, and interact with the physical world. I am advised by Prof. Ming-Ming Cheng and Prof. Qibin Hou, and previously worked at ByteDance's Volcano Engine Multimedia Laboratory.

Video MLLMs RL Post-Training Embodied Agents Spatial Intelligence Open-World Perception

Featured research

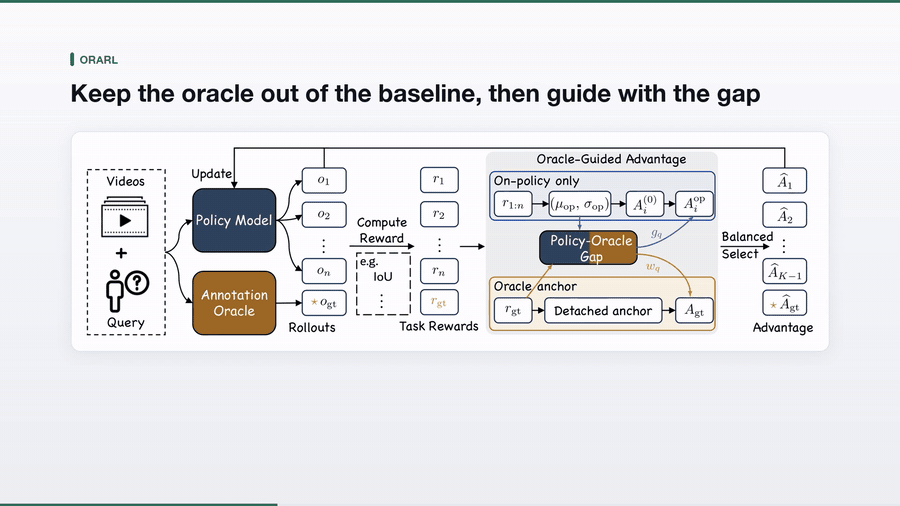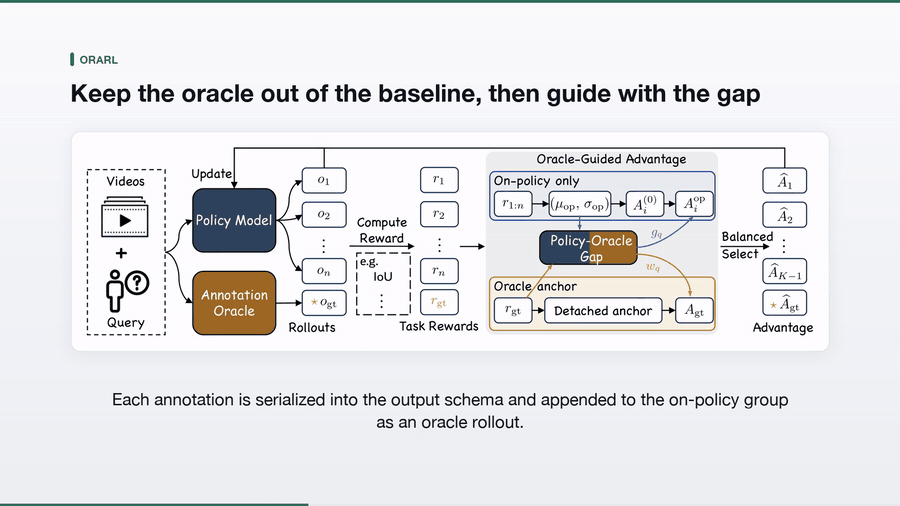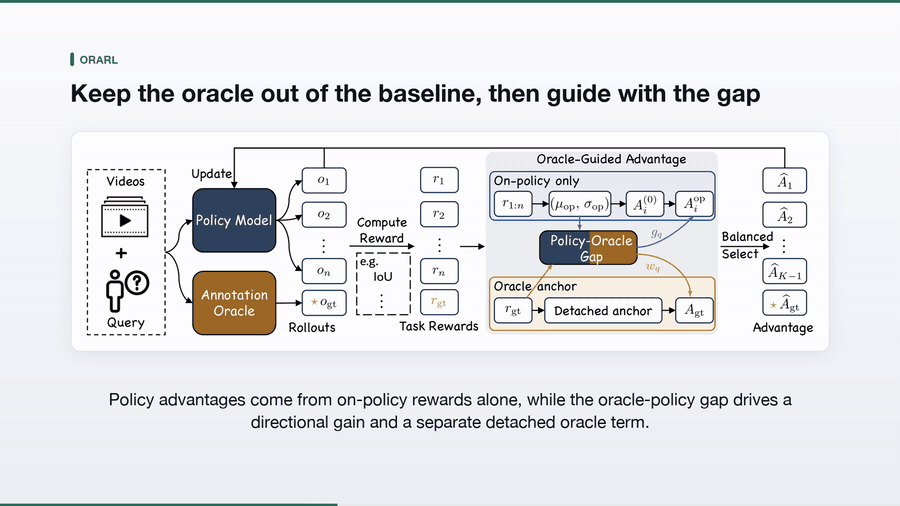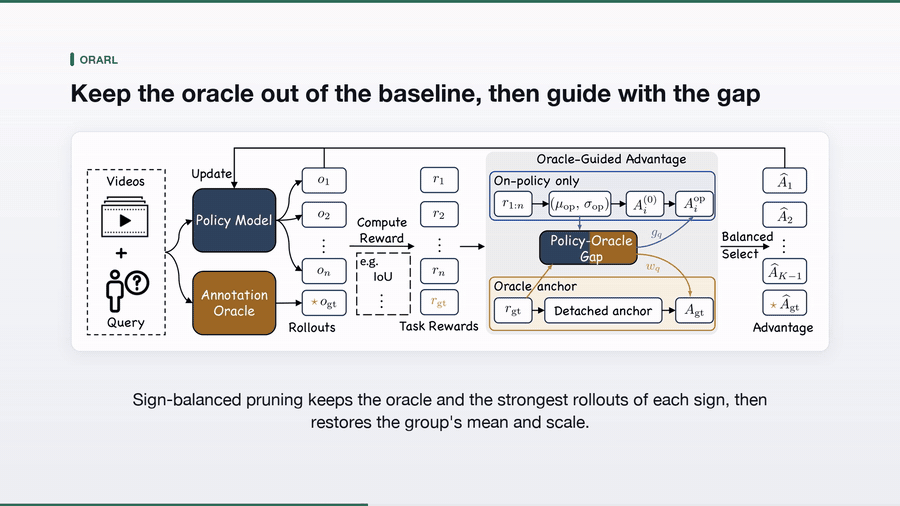
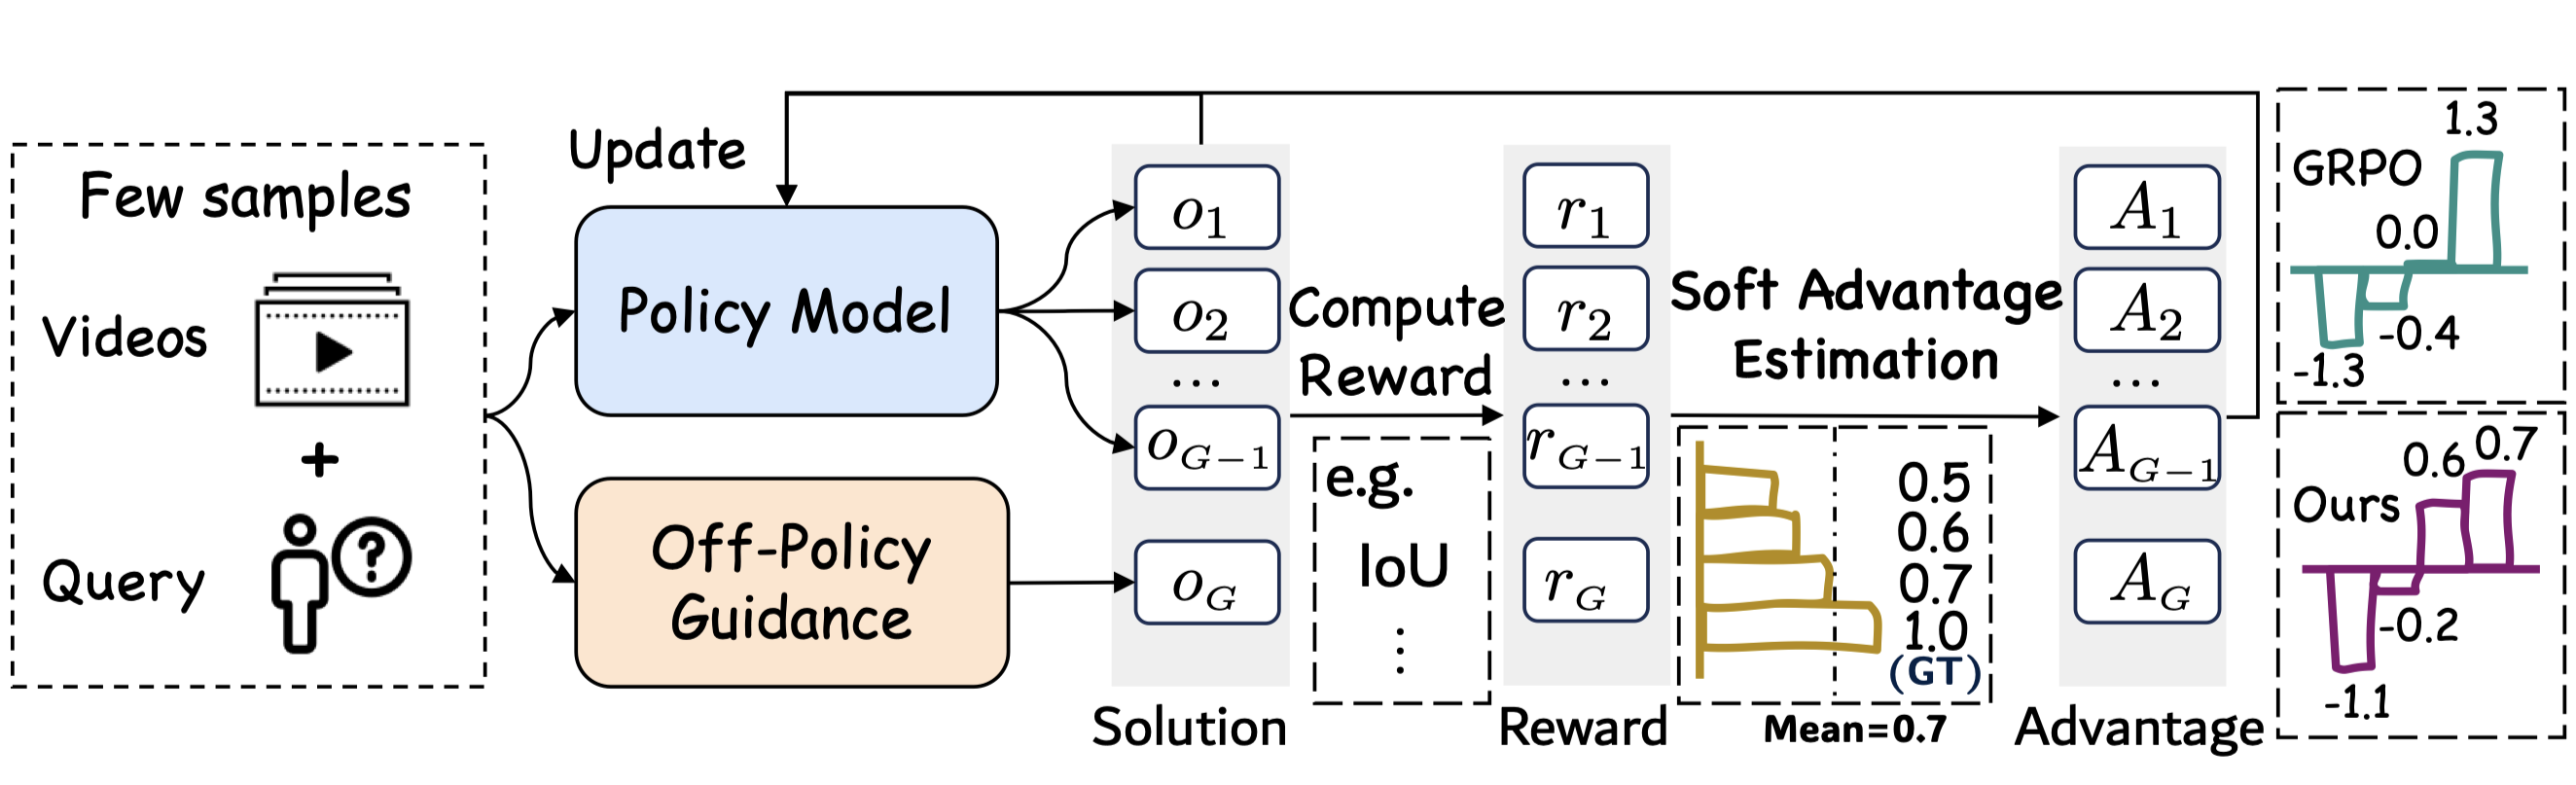
OraRL

Annotations as Rollouts

Efficient and scalable reinforcement learning across seven video-perception task families, without chain-of-thought decoding.

Paper Code Data Model

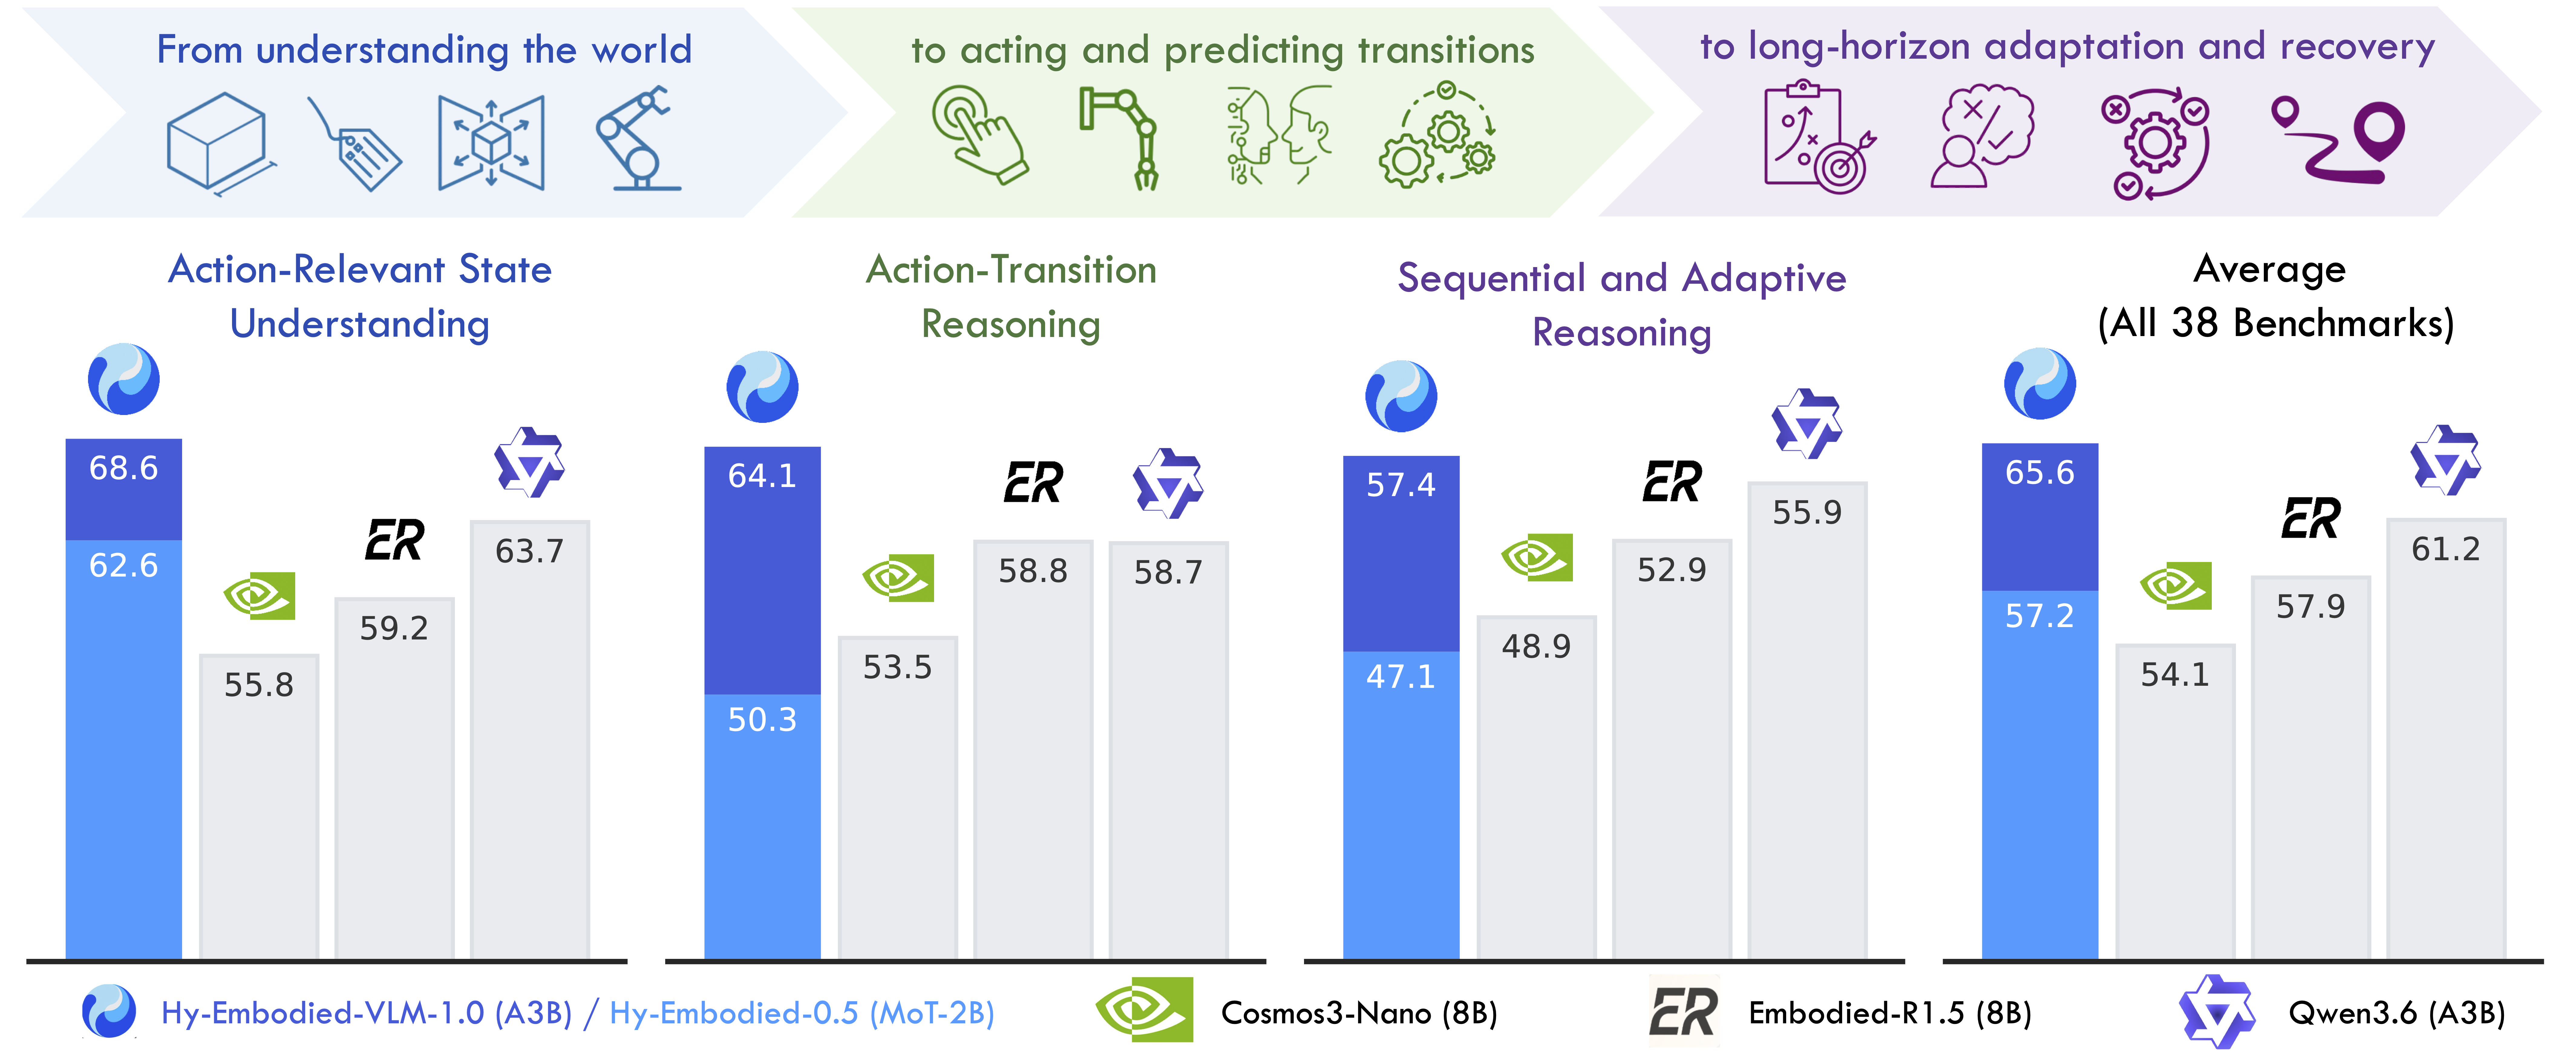
Hy-Embodied-VLM-1.0

Efficient Physical-World Agents

An efficient MoE foundation model for action-centric perception, multi-turn interaction, and long-horizon embodied reasoning.

Paper Code Model

TempSamp-R1

NeurIPS 2025

Reinforcement fine-tuning with effective temporal sampling for precise video temporal grounding.

Paper Code Models

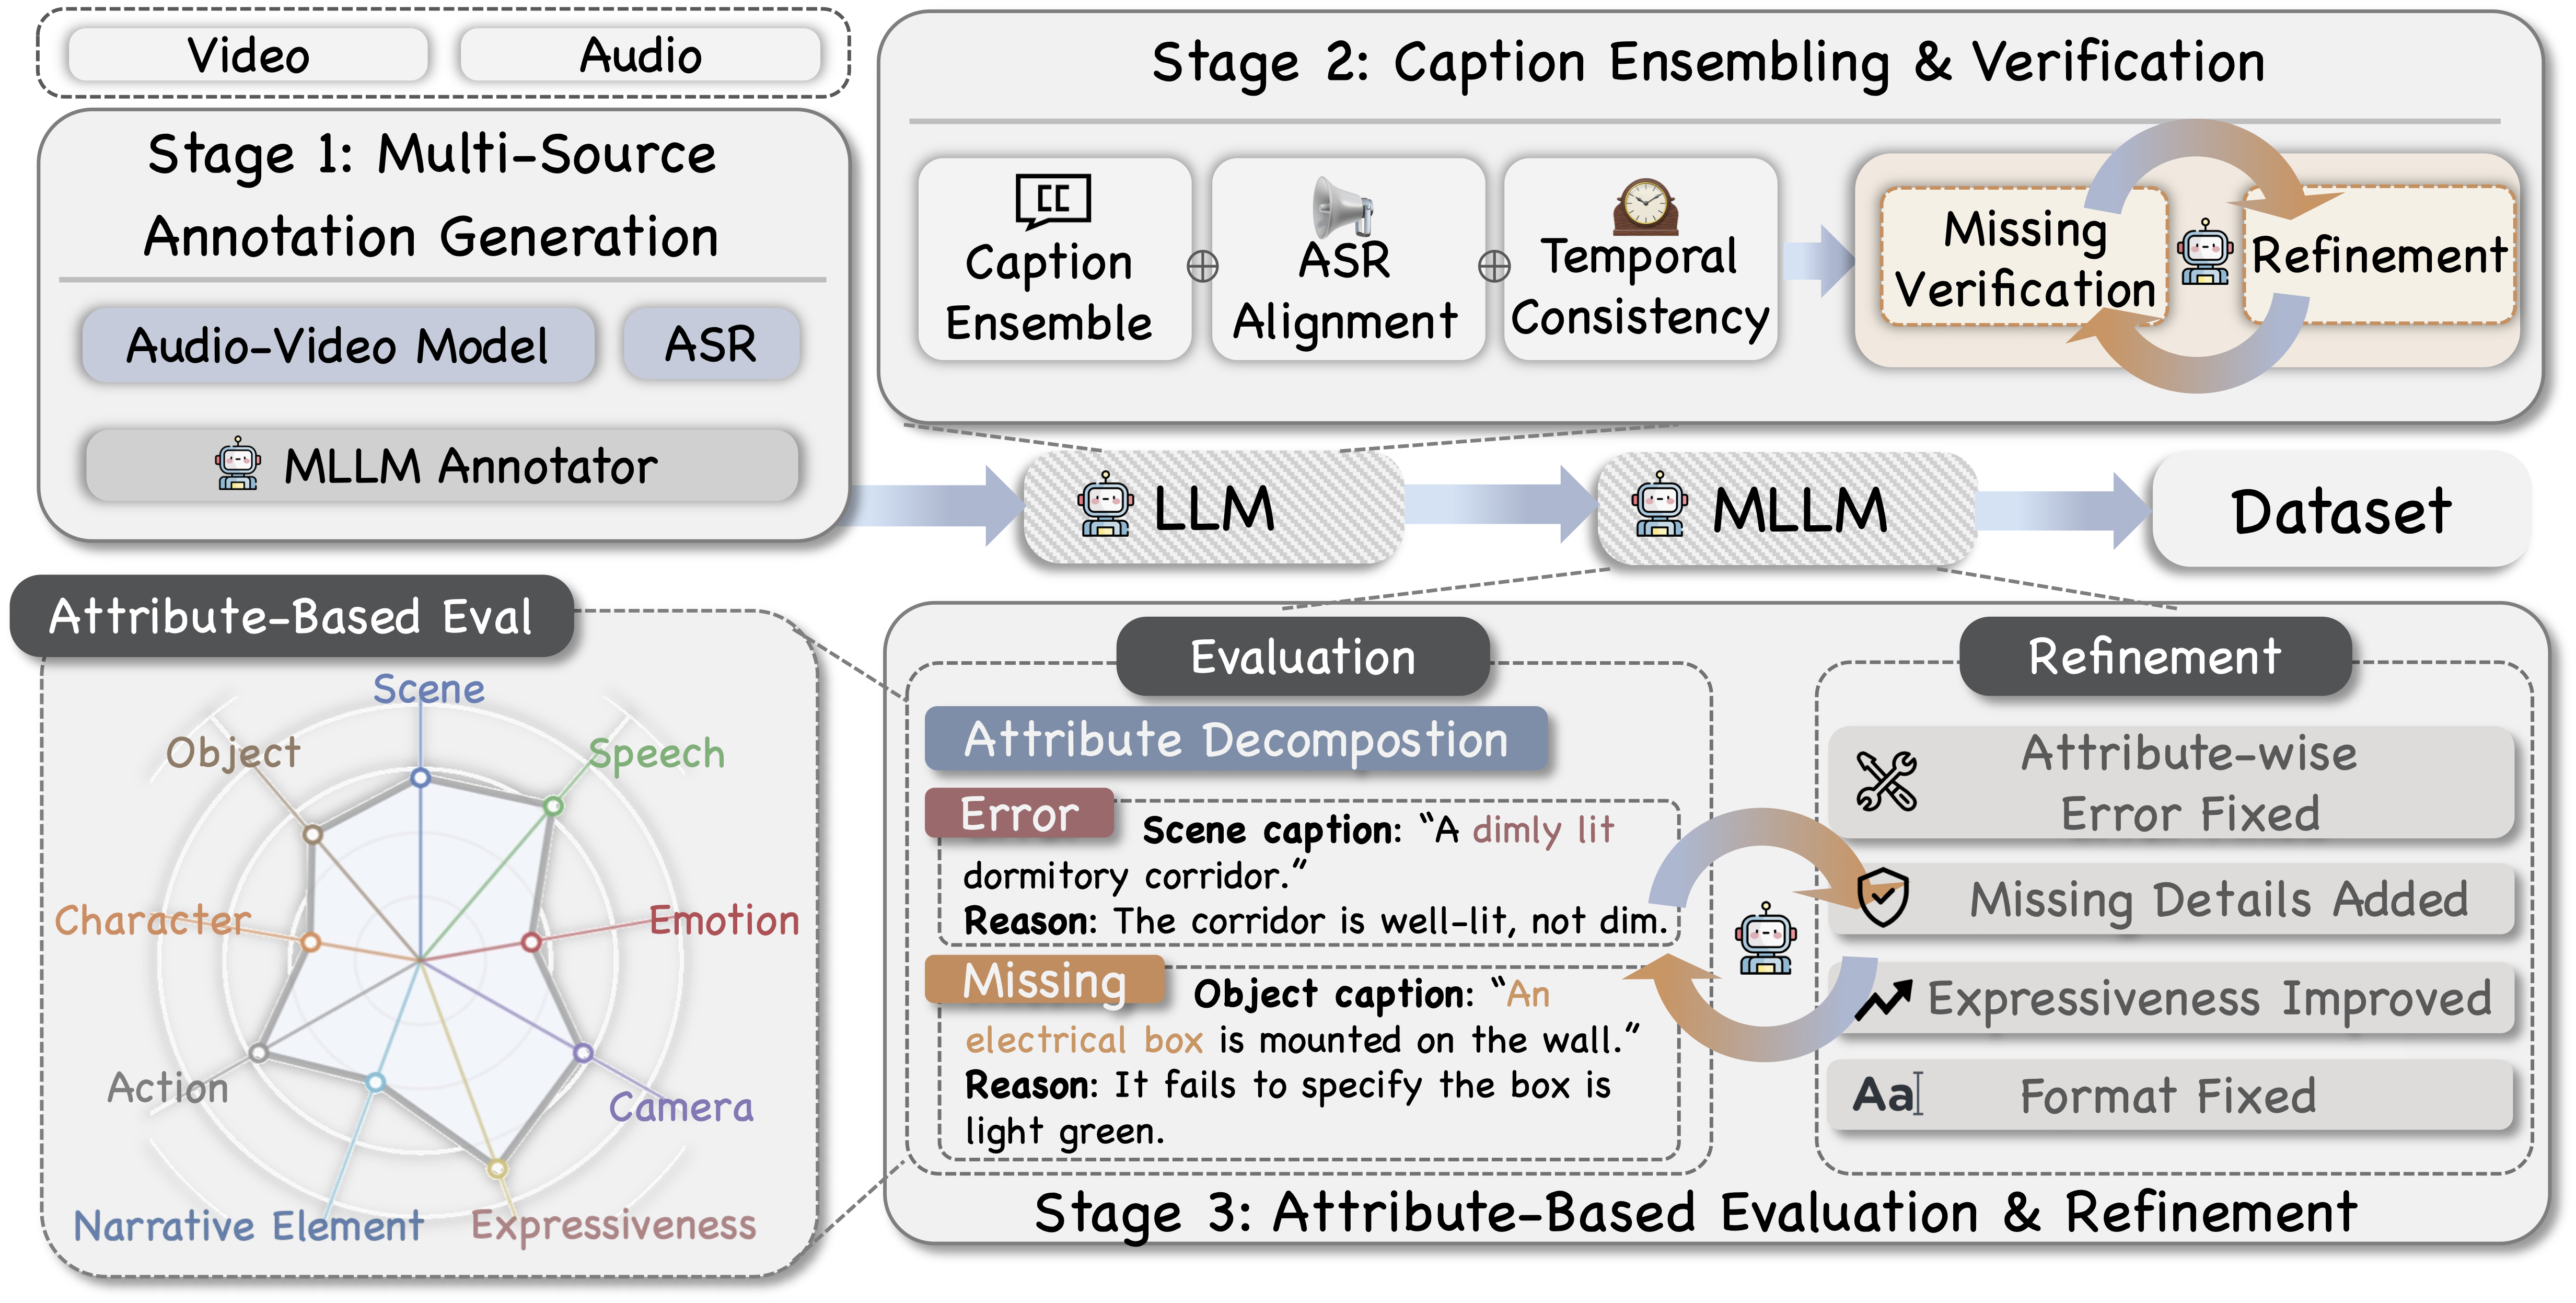
ASID-Caption

Universal Video MLLMs

Attribute-structured and quality-verified data and models for fine-grained audiovisual video understanding.

Paper Code Dataset

See my academic homepage for the full publication list, projects, and resources.

Open to conversations and collaborations on multimodal, embodied, and physical AI.

Pinned Loading

  1. HVision-NKU/OraRL HVision-NKU/OraRL Public

    🎬 OraRL — Annotations as Rollouts for efficient, scalable reinforcement learning of unified video MLLMs.

    Python 157 3

  2. Tencent-Hunyuan/HY-Embodied Tencent-Hunyuan/HY-Embodied Public

    HY-Embodied: Embodied Foundation Models for Real-World Agents

    Python 871 17

  3. HVision-NKU/TempSamp-R1 HVision-NKU/TempSamp-R1 Public

    [Official, NeurIPS 2025] TempSamp-R1: Effective Temporal Sampling with Reinforcement Fine-Tuning for Video LLMs.

    Python 26 3

  4. HVision-NKU/ASID-Caption HVision-NKU/ASID-Caption Public

    ASID-Caption: Attribute-Structured and Quality-Verified Audiovisual Instruction Dataset and Training Pipeline for Fine-Grained Video Understanding.

    Python 71 2

  5. HVision-NKU/DenseVLM HVision-NKU/DenseVLM Public

    [ICCV 2025] Unbiased Region-Language Alignment for Open-Vocabulary Dense Prediction

    Python 53 1

  6. HVision-NKU/Cascade-CLIP HVision-NKU/Cascade-CLIP Public

    Official implement of ICML2024 Cascade-CLIP: Cascaded Vision-Language Embeddings Alignment for Zero-Shot Semantic Segmentation

    Python 58 3