
Self-hosted AI Package is an open, docker compose template that quickly bootstraps a fully featured Local AI and Low Code development environment including Ollama for your local LLMs, Open WebUI for an interface to chat with your N8N agents, and Supabase for your database, vector store, and authentication.
This is Cole's version with a couple of improvements and the addition of Supabase, Open WebUI, Flowise, Neo4j, Langfuse, SearXNG, and Caddy! Also, the local RAG AI Agent workflows from the video will be automatically in your n8n instance if you use this setup instead of the base one provided by n8n!
IMPORANT: Supabase has updated a couple environment variables so you may have to add some new default values in your .env that I have in my .env.example if you have had this project up and running already and are just pulling new changes. Specifically, you need to add "POOLER_DB_POOL_SIZE=5" to your .env. This is required if you have had the package running before June 14th.
-
Local AI community forum over in the oTTomator Think Tank
-
GitHub Kanban board for feature implementation and bug squashing.
-
Original Local AI Starter Kit by the n8n team
-
Download my N8N + OpenWebUI integration directly on the Open WebUI site. (more instructions below)
Forked from Cole Medin's coleam00/local-ai-packaged repository and heavy modified with modules from theaiautomators/insights-lm-local-package and CoreWorxLab/CAAL Curated by https://github.com/mariowi, it combines the self-hosted n8n platform with a curated list of compatible AI products and components to quickly get started with building self-hosted AI workflows.
✅ Self-hosted n8n - Low-code platform with over 400 integrations and advanced AI components
✅ Supabase - Open source database as a service - most widely used database for AI agents
✅ Ollama - Cross-platform LLM platform to install and run the latest local LLMs
✅ Open WebUI - ChatGPT-like interface to privately interact with your local models and N8N agents
✅ Flowise - No/low code AI agent builder that pairs very well with n8n
✅ Qdrant - Open source, high performance vector store with an comprehensive API. Even though you can use Supabase for RAG, this was kept unlike Postgres since it's faster than Supabase so sometimes is the better option.
✅ Neo4j - Knowledge graph engine that powers tools like GraphRAG, LightRAG, and Graphiti
✅ SearXNG - Open source, free internet metasearch engine which aggregates results from up to 229 search services. Users are neither tracked nor profiled, hence the fit with the local AI package.
✅ Caddy - Managed HTTPS/TLS for custom domains
✅ Langfuse - Open source LLM engineering platform for agent observability
✅ Clickhouse - Open source column-oriented DBMS for online analytical processingthat allows users to generate analytical reports using SQL queries in real-time.
✅ Minio - Open source high-performance, S3 compatible object store
✅ PostgreSQL - Open source, powerful object-relational database system
✅ Redis - is an in-memory key–value database
✅ Docling - OCR and document parsing service for extracting structured data from documents
✅ LiveKit - Open source project that provides scalable, multi-user conferencing based on WebRTC
✅ Speaches - OpenAI API-compatible server supporting streaming transcription, translation, and speech generation
✅ Kokoro-FastAPI - Dockerized FastAPI wrapper for Kokoro-82M text-to-speech model w/CPU ONNX and NVIDIA GPU PyTorch support, handling, and auto-stitching
✅ Ollama-Proxy - Open source proxy server for multiple ollama instances with Key security
✅ InsightsLM - Open source, fully private and local alternative to NotebookLM. Chat with your documents, generate audio summaries, and ground AI in your own sources.
✅ CAAL - Local voice assistant that learns new abilities via auto-discovered n8n workflows exposed as tools via MCP
Before you begin, make sure you have the following software installed:
- Python
- Git or GitHub Desktop
- Docker or Docker Desktop
- A code editor like VS Code is highly recommended.
-
Clone the Base Local AI Package Repo
- Open your terminal or VS Code and clone Cole Medin's local-ai-packaged repository. This forms the foundation of our local setup.
git clone https://github.com/coleam00/local-ai-packaged.git cd local-ai-packaged -
Configure Environment Variables
- In the root of the
local-ai-packageddirectory, make a copy of.env.exampleand rename it to.env. - Populate the necessary secrets (n8n secrets, postgres password, etc.) as described in Cole's repo. You can use a password generator for secure keys.
- Generate the Supabase
JWT_SECRET,ANON_KEY, andSERVICE_ROLE_KEYusing the instructions in the documentation.
- In the root of the
-
Start the Services
- Open up Docker Desktop
- Run the start script provided in Cole's repository. Use the command appropriate for your system (e.g., Nvidia GPU). This will download all the necessary Docker images and start the containers. This may take a while.
# Example for Nvidia GPU python start_services.py --profile gpu-nvidia -
Import Supabase Script
- Login to your Supabase instance (usually at
http://localhost:8000) - Go to SQL Editor
- Paste the contents of the file located in
insights-lm-local-package/supabase-migration.sqlinto the SQL editor and click Run - You should get a "Success. No rows returned" message
- Login to your Supabase instance (usually at
-
Move Supabase Functions
- Once the Docker images have downloaded and the service are up, navigate to the
insights-lm-local-package/supabase/functions/directory. - Copy all the function folders within it.
- Paste them into the
supabase/volumes/functions/directory.
- Once the Docker images have downloaded and the service are up, navigate to the
-
Update Supabase Docker Configuration
- Open the
supabase/docker/docker-compose.ymlfile. - Copy the environment variables listed in
insights-lm-local-package/supabase/docker-compose.yml.copy. - Paste these variables under the
functionsservice in thesupabase/docker/docker-compose.ymlfile. This gives the edge functions access to your N8N webhook URLs.
- Open the
-
Restart Docker Containers
- Shut down all running services using the provided command.
# Example for Nvidia GPU docker compose -p localai -f docker-compose.yml --profile gpu-nvidia down- Restart the services using the
start_services.pyscript again to apply all changes.
-
Import and Configure N8N Workflows
- Access N8N in your browser (usually at
http://localhost:5678). - Create a new workflow and import the
Import_Insights_LM_Workflows.jsonfile from theinsights-lm-local-package/n8n/directory. - Follow the steps in the video to configure the importer workflow.
- Create an N8N API Key and set the credential in the N8N node
- URL should be "http://localhost:5678/api/v1"
- Create credential for Webhook Header Auth and copy the credential ID into the "Enter User Values" node
- Name must be "Authorization" and value is what was set at the bottom of the ENV file
- Create credential for Supabase API and copy the credential ID into the "Enter User Values" node
- Host should be "http://kong:8000"
- Service Role Secret is in your ENV file
- Create credential for Olama and copy the credential ID into the "Enter User Values" node
- Base URL should be "http://ollama:11434"
- Create an N8N API Key and set the credential in the N8N node
- Run the importer workflow to automatically set up all the required InsightsLM workflows in your N8N instance.
- Access N8N in your browser (usually at
-
Activate Workflows & Test
- Go to your N8N dashboard, find the newly imported workflows, and activate them all (Except the "Extract Text" workflow).
- Access the InsightsLM frontend (usually at
http://localhost:3010). - Create a user in your local Supabase dashboard (under Authentication) to log in.
- You're all set! Start uploading documents and chatting with your private AI assistant.
Before running the services, you need to set up your environment variables for Supabase following their self-hosting guide.
- Make a copy of
.env.exampleand rename it to.envin the root directory of the project - Set the following required environment variables:
############
# N8N Configuration
############
N8N_ENCRYPTION_KEY=
N8N_USER_MANAGEMENT_JWT_SECRET=

############
# Supabase Secrets
############
POSTGRES_PASSWORD=
JWT_SECRET=
ANON_KEY=
SERVICE_ROLE_KEY=
DASHBOARD_USERNAME=
DASHBOARD_PASSWORD=
POOLER_TENANT_ID=

############
# Neo4j Secrets
############
NEO4J_AUTH=

############
# Langfuse credentials
############

CLICKHOUSE_PASSWORD=
MINIO_ROOT_PASSWORD=
LANGFUSE_SALT=
NEXTAUTH_SECRET=
ENCRYPTION_KEY=
Important
Make sure to generate secure random values for all secrets. Never use the example values in production.
- Set the following environment variables if deploying to production, otherwise leave commented:
############
# Caddy Config
############

N8N_HOSTNAME=n8n.yourdomain.com
WEBUI_HOSTNAME=:openwebui.yourdomain.com
FLOWISE_HOSTNAME=:flowise.yourdomain.com
SUPABASE_HOSTNAME=:supabase.yourdomain.com
OLLAMA_HOSTNAME=:ollama.yourdomain.com
SEARXNG_HOSTNAME=searxng.yourdomain.com
NEO4J_HOSTNAME=neo4j.yourdomain.com
LETSENCRYPT_EMAIL=your-email-address
The project includes a start_services.py script that handles starting both the Supabase and local AI services. The script accepts a --profile flag to specify which GPU configuration to use.
python start_services.py --profile gpu-nvidiaNote
If you have not used your Nvidia GPU with Docker before, please follow the Ollama Docker instructions.
python start_services.py --profile gpu-amdIf you're using a Mac with an M1 or newer processor, you can't expose your GPU to the Docker instance, unfortunately. There are two options in this case:
-
Run the starter kit fully on CPU:
python start_services.py --profile cpu
-
Run Ollama on your Mac for faster inference, and connect to that from the n8n instance:
python start_services.py --profile none
If you want to run Ollama on your mac, check the Ollama homepage for installation instructions.
If you're running OLLAMA locally on your Mac (not in Docker), you need to modify the OLLAMA_HOST environment variable in the n8n service configuration. Update the x-n8n section in your Docker Compose file as follows:
x-n8n: &service-n8n
  # ... other configurations ...
  environment:
    # ... other environment variables ...
    - OLLAMA_HOST=host.docker.internal:11434
Additionally, after you see "Editor is now accessible via: http://localhost:5678/":
- Head to http://localhost:5678/home/credentials
- Click on "Local Ollama service"
- Change the base URL to "http://host.docker.internal:11434/"
python start_services.py --profile cpuThe start-services.py script offers the possibility to pass one of two options for the environment argument, private (default environment) and public:
- private: you are deploying the stack in a safe environment, hence a lot of ports can be made accessible without having to worry about security
- public: the stack is deployed in a public environment, which means the attack surface should be made as small as possible. All ports except for 80 and 443 are closed
The stack initialized with
python start_services.py --profile gpu-nvidia --environment privateequals the one initialized with
python start_services.py --profile gpu-nvidia- Linux machine (preferably Unbuntu) with Nano, Git, and Docker installed
Before running the above commands to pull the repo and install everything:
-
Run the commands as root to open up the necessary ports:
- ufw enable
- ufw allow 80 && ufw allow 443
- ufw reload
WARNING
ufw does not shield ports published by docker, because the iptables rules configured by docker are analyzed before those configured by ufw. There is a solution to change this behavior, but that is out of scope for this project. Just make sure that all traffic runs through the caddy service via port 443. Port 80 should only be used to redirect to port 443.
-
Run the start-services.py script with the environment argument public to indicate you are going to run the package in a public environment. The script will make sure that all ports, except for 80 and 443, are closed down, e.g.
python3 start_services.py --profile gpu-nvidia --environment public-
Set up A records for your DNS provider to point your subdomains you'll set up in the .env file for Caddy to the IP address of your cloud instance.
For example, A record to point n8n to [cloud instance IP] for n8n.yourdomain.com
NOTE: If you are using a cloud machine without the "docker compose" command available by default, such as a Ubuntu GPU instance on DigitalOcean, run these commands before running start_services.py:
- DOCKER_COMPOSE_VERSION=$(curl -s https://api.github.com/repos/docker/compose/releases/latest | grep 'tag_name' | cut -d\" -f4)
- sudo curl -L "https://github.com/docker/compose/releases/download/${DOCKER_COMPOSE_VERSION}/docker-compose-linux-x86_64" -o /usr/local/bin/docker-compose
- sudo chmod +x /usr/local/bin/docker-compose
- sudo mkdir -p /usr/local/lib/docker/cli-plugins
- sudo ln -s /usr/local/bin/docker-compose /usr/local/lib/docker/cli-plugins/docker-compose
The main component of the self-hosted AI starter kit is a docker compose file pre-configured with network and disk so there isn’t much else you need to install. After completing the installation steps above, follow the steps below to get started.
-
Open http://localhost:5678/ in your browser to set up n8n. You’ll only have to do this once. You are NOT creating an account with n8n in the setup here, it is only a local account for your instance!
-
Open the included workflow: http://localhost:5678/workflow/vTN9y2dLXqTiDfPT
-
Create credentials for every service:
Ollama URL: http://ollama:11434
Postgres (through Supabase): use DB, username, and password from .env. IMPORTANT: Host is 'db' Since that is the name of the service running Supabase
Qdrant URL: http://qdrant:6333 (API key can be whatever since this is running locally)
Google Drive: Follow this guide from n8n. Don't use localhost for the redirect URI, just use another domain you have, it will still work! Alternatively, you can set up local file triggers.
-
Select Test workflow to start running the workflow.
-
If this is the first time you’re running the workflow, you may need to wait until Ollama finishes downloading Llama3.1. You can inspect the docker console logs to check on the progress.
-
Make sure to toggle the workflow as active and copy the "Production" webhook URL!
-
Open http://localhost:3000/ in your browser to set up Open WebUI. You’ll only have to do this once. You are NOT creating an account with Open WebUI in the setup here, it is only a local account for your instance!
-
Go to Workspace -> Functions -> Add Function -> Give name + description then paste in the code from
n8n_pipe.pyThe function is also published here on Open WebUI's site.
-
Click on the gear icon and set the n8n_url to the production URL for the webhook you copied in a previous step.
-
Toggle the function on and now it will be available in your model dropdown in the top left!
To open n8n at any time, visit http://localhost:5678/ in your browser. To open Open WebUI at any time, visit http://localhost:3000/.
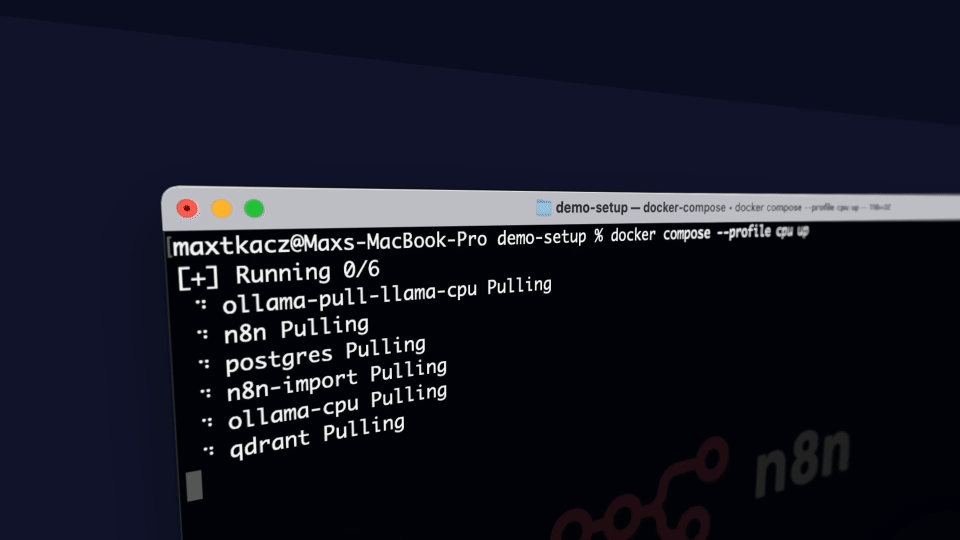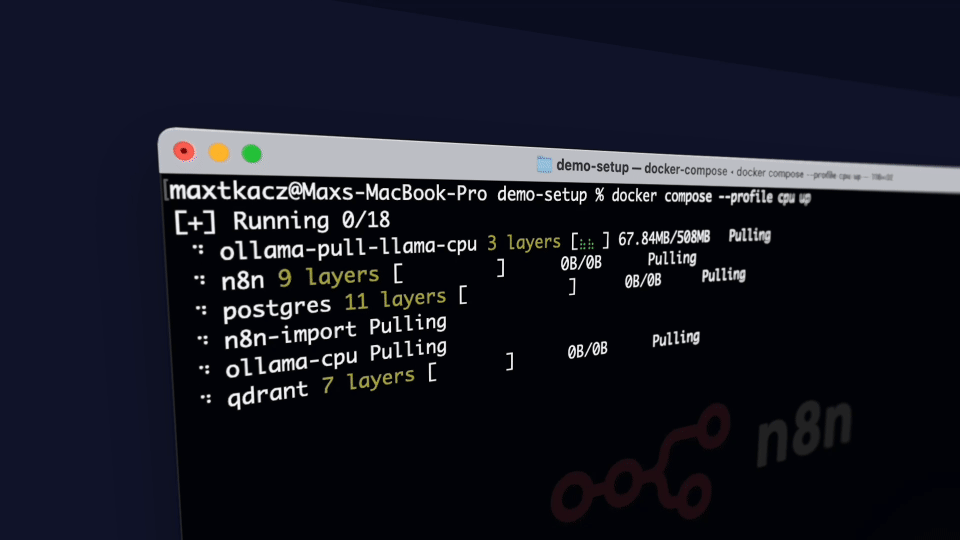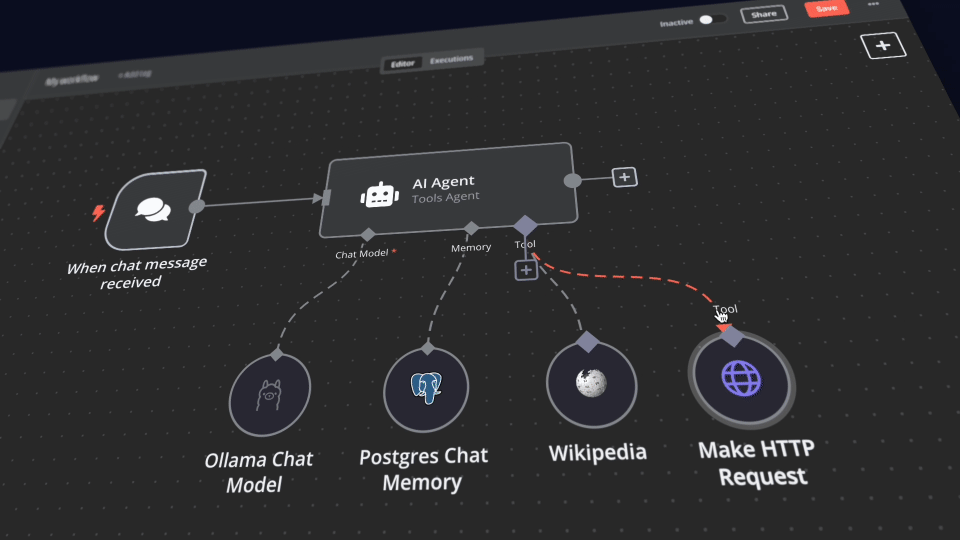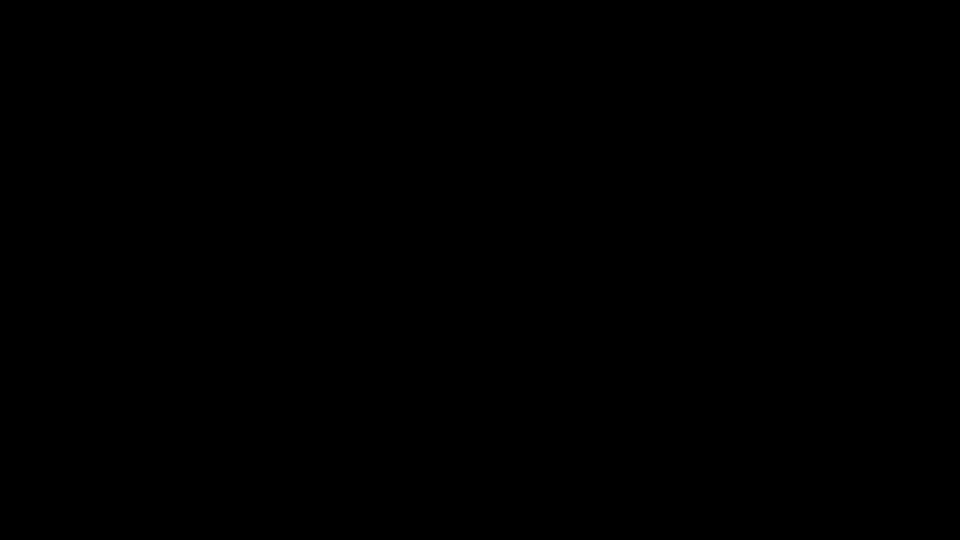
With your n8n instance, you’ll have access to over 400 integrations and a suite of basic and advanced AI nodes such as AI Agent, Text classifier, and Information Extractor nodes. To keep everything local, just remember to use the Ollama node for your language model and Qdrant as your vector store.
Note
This starter kit is designed to help you get started with self-hosted AI workflows. While it’s not fully optimized for production environments, it combines robust components that work well together for proof-of-concept projects. You can customize it to meet your specific needs
To update all containers to their latest versions (n8n, Open WebUI, etc.), run these commands:
# Stop all services
docker compose -p localai -f docker-compose.yml --profile <your-profile> down

# Pull latest versions of all containers
docker compose -p localai -f docker-compose.yml --profile <your-profile> pull

# Start services again with your desired profile
python start_services.py --profile <your-profile>
Replace <your-profile> with one of: cpu, gpu-nvidia, gpu-amd, or none.
Note: The start_services.py script itself does not update containers - it only restarts them or pulls them if you are downloading these containers for the first time. To get the latest versions, you must explicitly run the commands above.
Here are solutions to common issues you might encounter:
-
Supabase Pooler Restarting: If the supabase-pooler container keeps restarting itself, follow the instructions in this GitHub issue.
-
Supabase Analytics Startup Failure: If the supabase-analytics container fails to start after changing your Postgres password, delete the folder
supabase/docker/volumes/db/data. -
If using Docker Desktop: Go into the Docker settings and make sure "Expose daemon on tcp://localhost:2375 without TLS" is turned on
-
Supabase Service Unavailable - Make sure you don't have an "@" character in your Postgres password! If the connection to the kong container is working (the container logs say it is receiving requests from n8n) but n8n says it cannot connect, this is generally the problem from what the community has shared. Other characters might not be allowed too, the @ symbol is just the one I know for sure!
-
SearXNG Restarting: If the SearXNG container keeps restarting, run the command "chmod 755 searxng" within the local-ai-packaged folder so SearXNG has the permissions it needs to create the uwsgi.ini file.
-
Files not Found in Supabase Folder - If you get any errors around files missing in the supabase/ folder like .env, docker/docker-compose.yml, etc. this most likely means you had a "bad" pull of the Supabase GitHub repository when you ran the start_services.py script. Delete the supabase/ folder within the Local AI Package folder entirely and try again.
-
Windows GPU Support: If you're having trouble running Ollama with GPU support on Windows with Docker Desktop:
- Open Docker Desktop settings
- Enable WSL 2 backend
- See the Docker GPU documentation for more details
-
Linux GPU Support: If you're having trouble running Ollama with GPU support on Linux, follow the Ollama Docker instructions.
n8n is full of useful content for getting started quickly with its AI concepts and nodes. If you run into an issue, go to support.
- AI agents for developers: from theory to practice with n8n
- Tutorial: Build an AI workflow in n8n
- Langchain Concepts in n8n
- Demonstration of key differences between agents and chains
- What are vector databases?
For more AI workflow ideas, visit the official n8n AI template gallery. From each workflow, select the Use workflow button to automatically import the workflow into your local n8n instance.
- AI Agent Chat
- AI chat with any data source (using the n8n workflow too)
- Chat with OpenAI Assistant (by adding a memory)
- Use an open-source LLM (via HuggingFace)
- Chat with PDF docs using AI (quoting sources)
- AI agent that can scrape webpages
- Tax Code Assistant
- Breakdown Documents into Study Notes with MistralAI and Qdrant
- Financial Documents Assistant using Qdrant and Mistral.ai
- Recipe Recommendations with Qdrant and Mistral
The self-hosted AI starter kit will create a shared folder (by default,
located in the same directory) which is mounted to the n8n container and
allows n8n to access files on disk. This folder within the n8n container is
located at /data/shared -- this is the path you’ll need to use in nodes that
interact with the local filesystem.
Nodes that interact with the local filesystem
This project (originally created by the n8n team, link at the top of the README) is licensed under the Apache License 2.0 - see the LICENSE file for details.