Repository navigation
[GPU] make sure 3D weights case [ B, N, K] with [B, N, 1] scale/zp are treated as grouped case - #39268
Conversation


|
Azure Pipelines: There may be pipelines that require an authorized user to comment /azp run to run. Some pipeline(s) encountered errors during trigger evaluation. |
There was a problem hiding this comment.
🟡 Changes recommended
The new mask selection expects 1,024 zero points from a 16-value buffer for shared-expert inputs, risking invalid reads or incorrect results.
1 open issue

What changed in this PR
This PR addresses a GPU oneDNN compressed fully connected regression exposed by #38697, preserving per-expert quantization parameters for 3D weights with one group along K.
Changes:
- Uses the weights’ batch dimension to retain grouped zero-point handling.
- Applies batch-aware scale and zero-point mask selection during cache loading.
- Adds regression tests covering expert counts, parameter orientations, caching, and group counts.
| File | Description |
|---|---|
src/plugins/intel_gpu/tests/unit/test_cases/fully_connected_gpu_test.cpp |
Adds parameterized per-expert zero-point accuracy tests. |
src/plugins/intel_gpu/src/graph/impls/onednn/fully_connected_onednn.cpp |
Updates quantization mask selection for compilation and cache loading. |
Review effort: Balanced

|
Please fix the conflicts with master. |

 andrew-k-park
left a comment
andrew-k-park
left a comment
There was a problem hiding this comment.
I reviewed the PR and also tested it on A770, the same GPU as CI GPU_ARC_RPL. I built the GPU plugin from your PR head, loaded it into the private-build wheels of the PR base (8f0a334), and ran the deepseek-ocr-2 INT8_ASYM model with the CI WWB command:
- WWB similarity: 0.712 on the base, 0.893 with your PR (WW42: 0.885, CPU: 0.897).
LGTM
…ress with grouped mask

 e-ddykim
left a comment
e-ddykim
left a comment
There was a problem hiding this comment.
Please check these regressions --> e-ddykim@f51e408

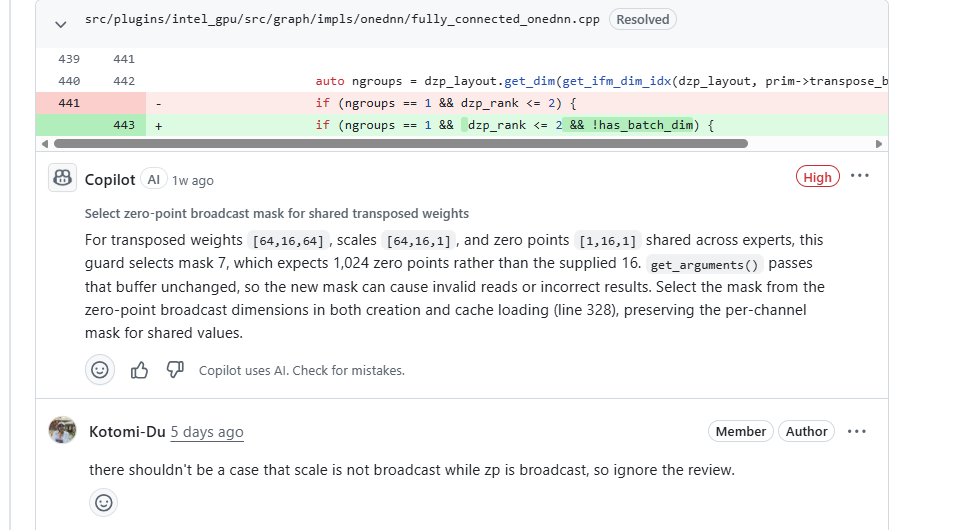
Thanks for the review. I saw the same concern raised by Copilot review as below. However, I don't think we need to take it because there is no such real case for now. The previous code never take care such case before as well. So, I don't think it is a regression introduced by this PR. Here are additional two concerns:
In general, I am more conservative and tend to not add new case coverage to complicate the code. If you still think it is a good approach to go, I can take care in the next PR to cover new case you posted. I suggest not to put in this PR. |
|
build_jenkins |

|
@Kotomi-Du The reason I called this a regression is that the test passes on the current master branch but fails when this PR is applied. However, if you're confident that this scenario cannot occur in practice, I don't think we need to take any additional action here. |

understood, I guess the regression track is as below, so basically my refactor introduces regressions of MOE model while make it pass for zp share across expert case by accident.
|


Description
For weights [64, N, K] and zero points [64, N, 1], the old code incorrectly read N as the group count but accidentally selected a grouped mask that preserved per-expert zero points. After the PR #38697 correctly identified one group along K, the existing rank check selected a per-channel mask that ignored the expert axis, causing all experts to reuse the first expert’s zero points. The fix explicitly checks whether weights have a batch/expert dimension and retains the grouped mask for 3D weights, including during cache loading.
ngroupsDetails
Affected topology:
[64, N, K], withtranspose_b = true.[64, N, 1], withtranspose_b_zp = true.N > 1andK > 1, so the weights' non-unit dimension count is 3.Before the PR #38697: correct expert handling by accident
The old code chose the zero-point IFM axis using the number of non-unit zero-point dimensions:
Because
ngroups != 1, the code selected the grouped branch:For a 3D FC,
grouped = (1 << 3) - 1 = 7. This mask includes the expert dimension, so different experts retain their own zero points. The observed case worked, but the axis selection and inferred group count were wrong.After the PR #38697, before the fix: correct axis exposes the mask-selection bug
The new orientation-aware helper correctly identifies the IFM-group axis:
However, the per-channel condition still used the non-unit zero-point rank:
It didn't land to the condition which has group attribute.
After the fix in current PR
Mask selection now explicitly checks whether the weights have a batch/expert dimension:
For
[64, N, K],has_batch_dimistrue. Even withngroups == 1, the code keeps the grouped mask 7 and preserves per-expert zero points. Ordinary 2D per-channel weights still use the per-channel branch.The same batch-dimension check is applied to scale and zero-point attributes during cache loading, keeping grouped handling consistent with fresh compilation.
Ticket
AI Assistance: