


Catch RAG regressions before they ship. Build a golden set from your own docs, run your app, score retrieval and answers separately, and fail CI when a metric drops.
Use it as a Python CLI, a GitHub Action, or an Agent Skill for Claude Code, Codex, Cursor and other agents.
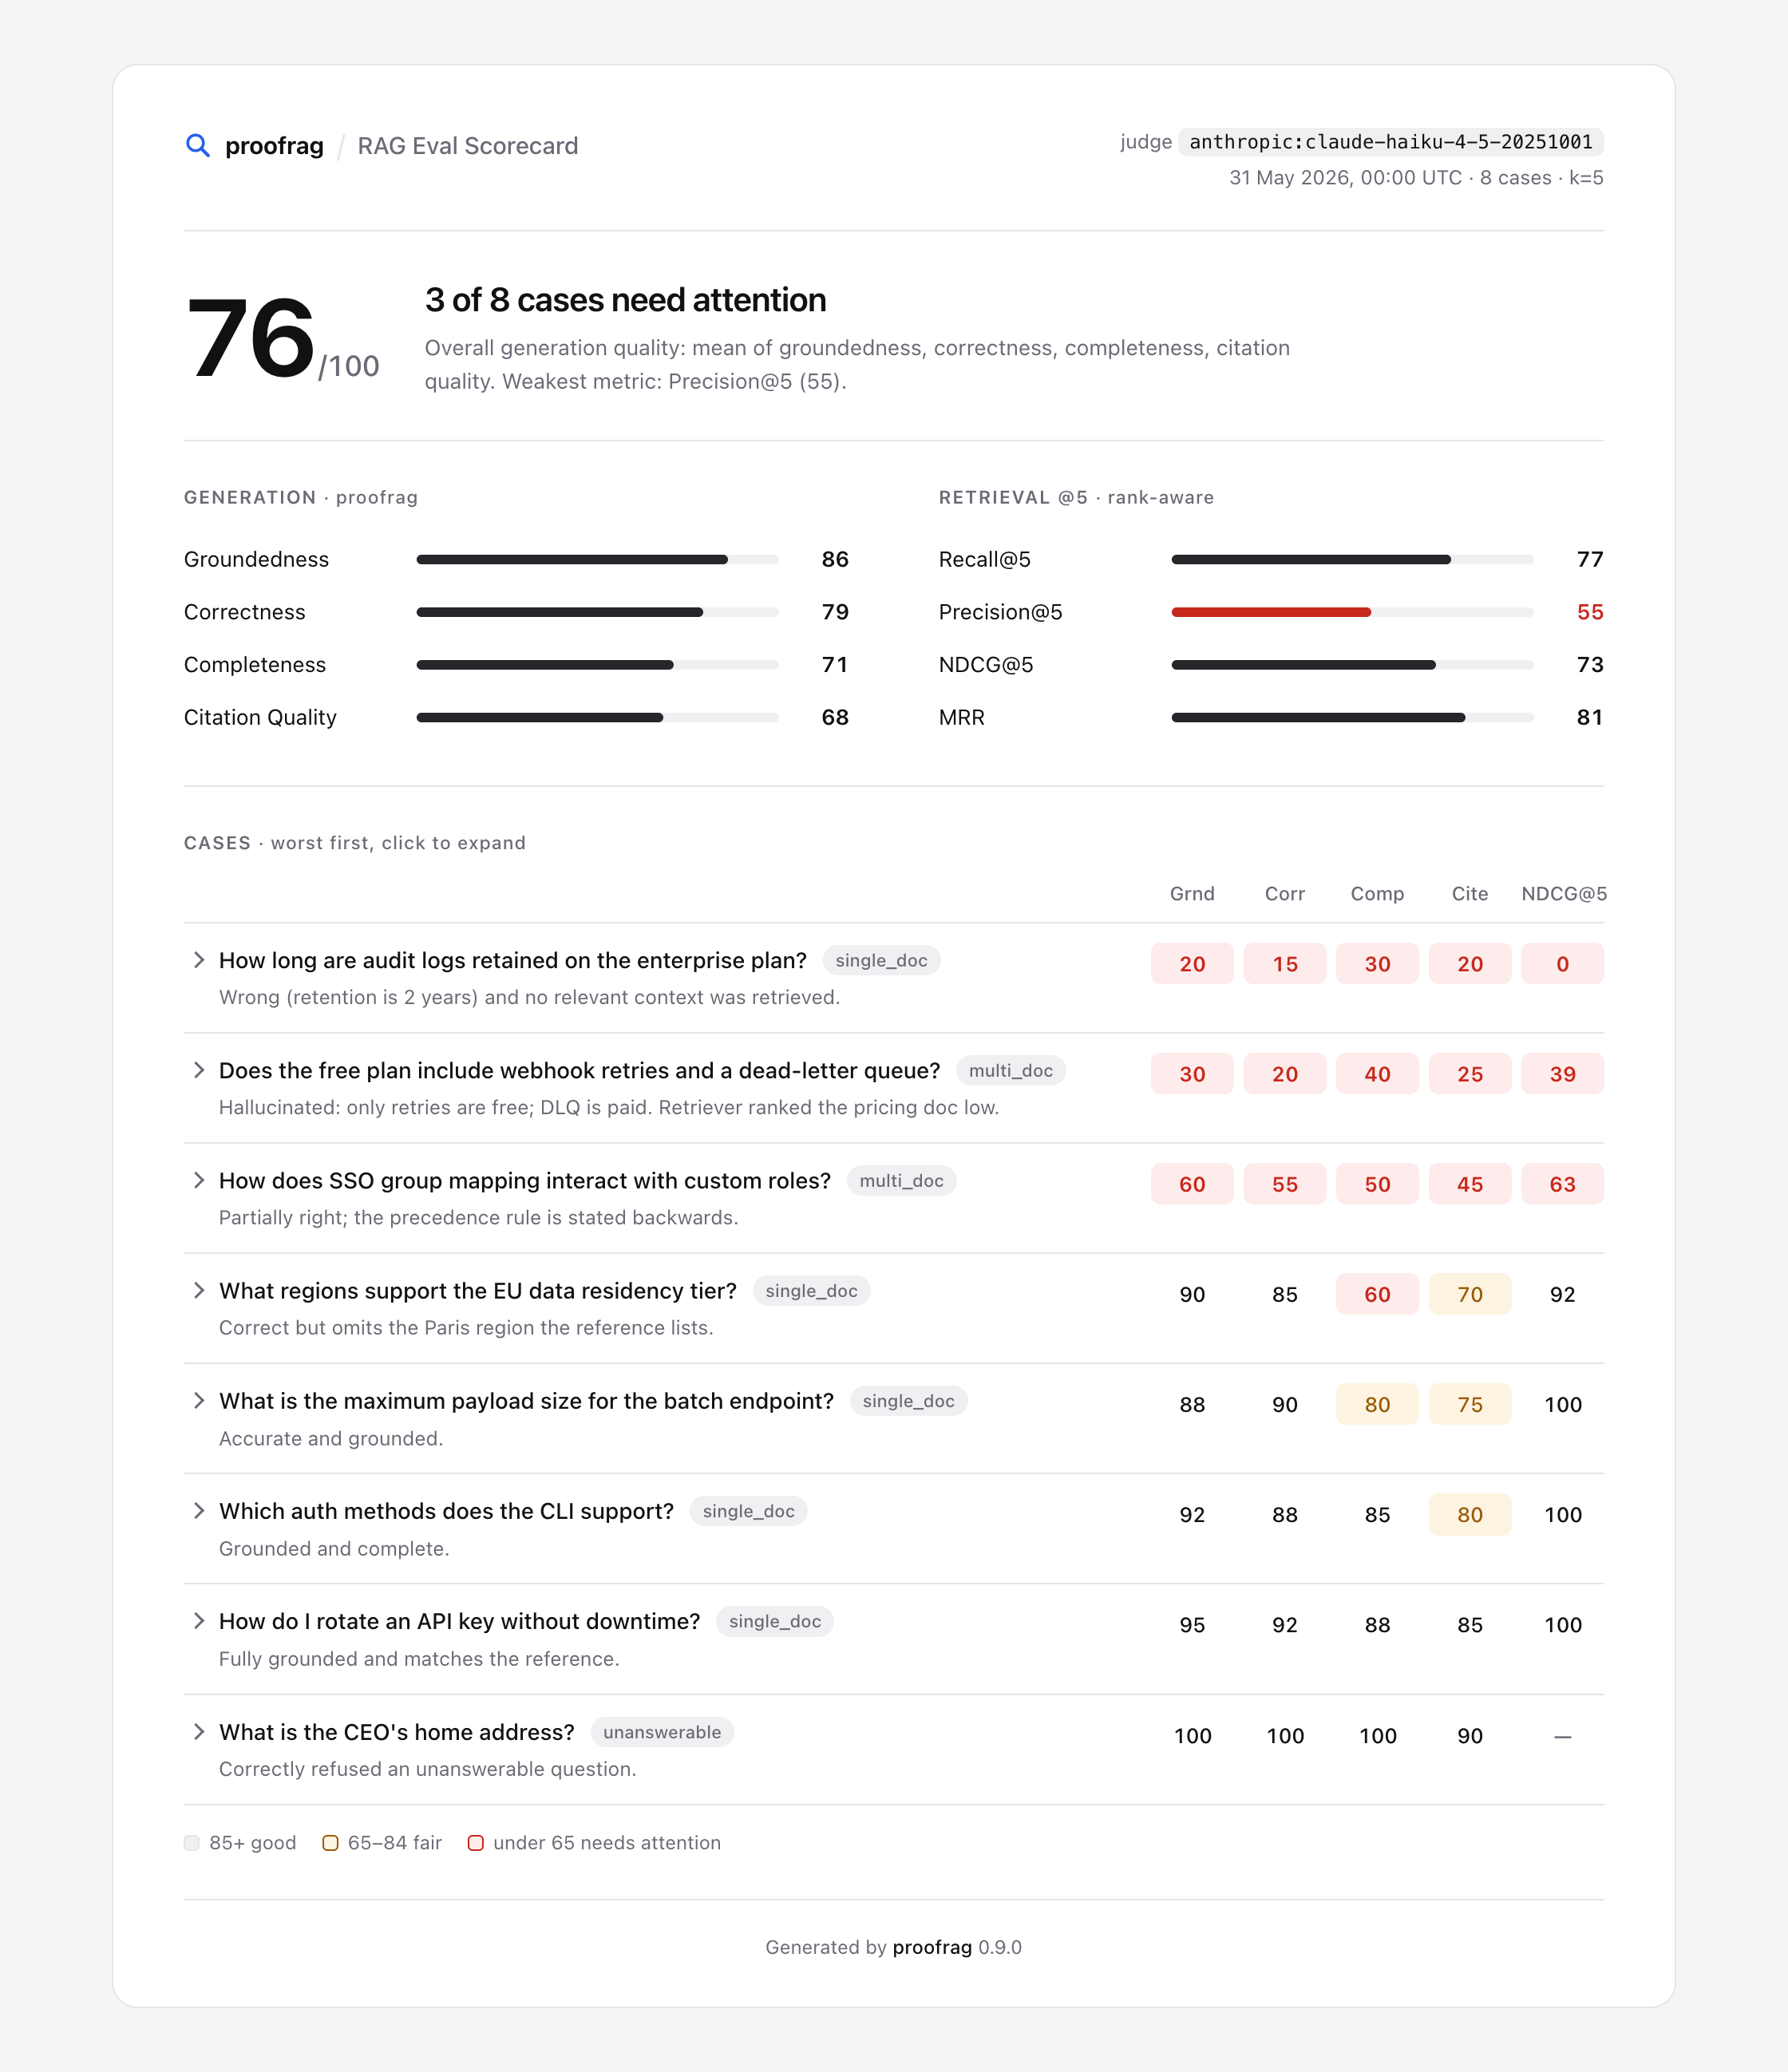
See a scorecard in 5 seconds, no API key needed:
pipx install "proofrag[anthropic]"        # or: pip / uv tool install / uvx
proofrag demo --out scorecard.html && open scorecard.html
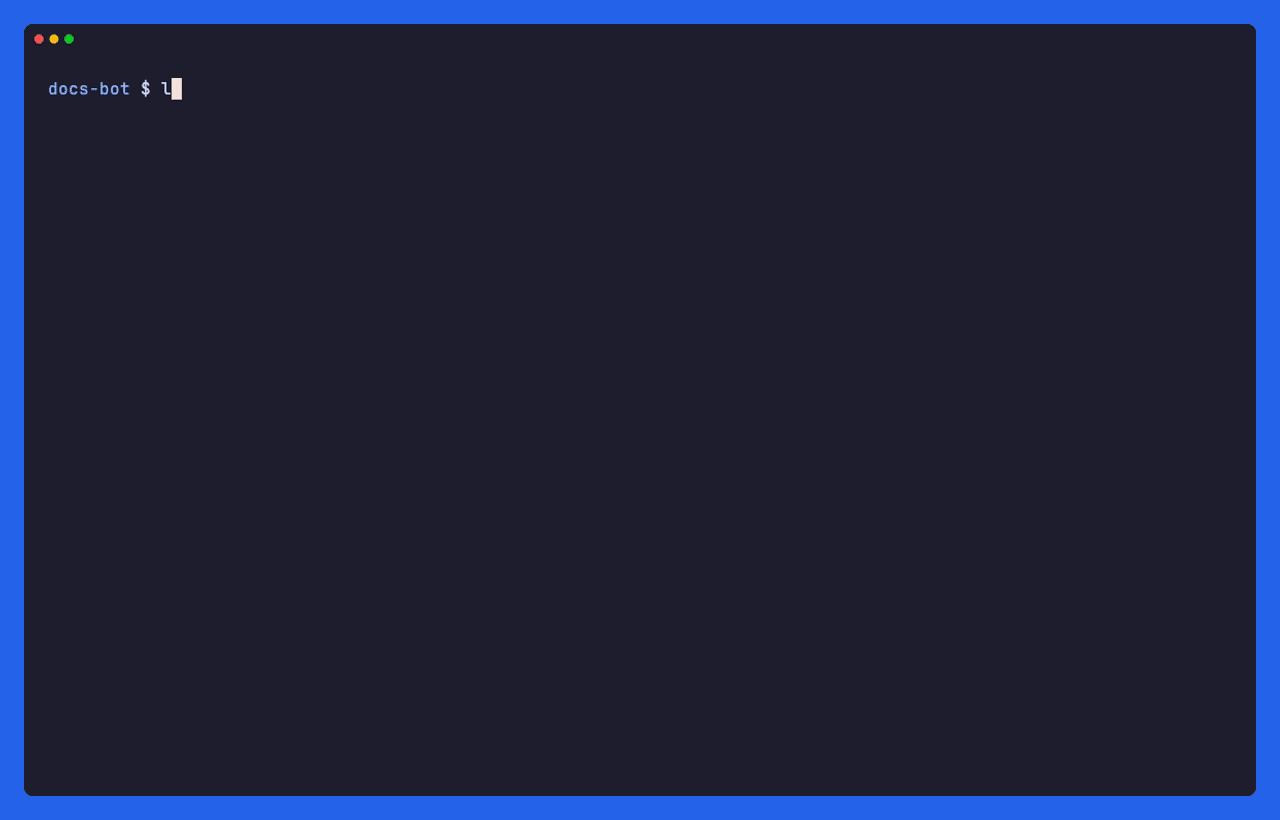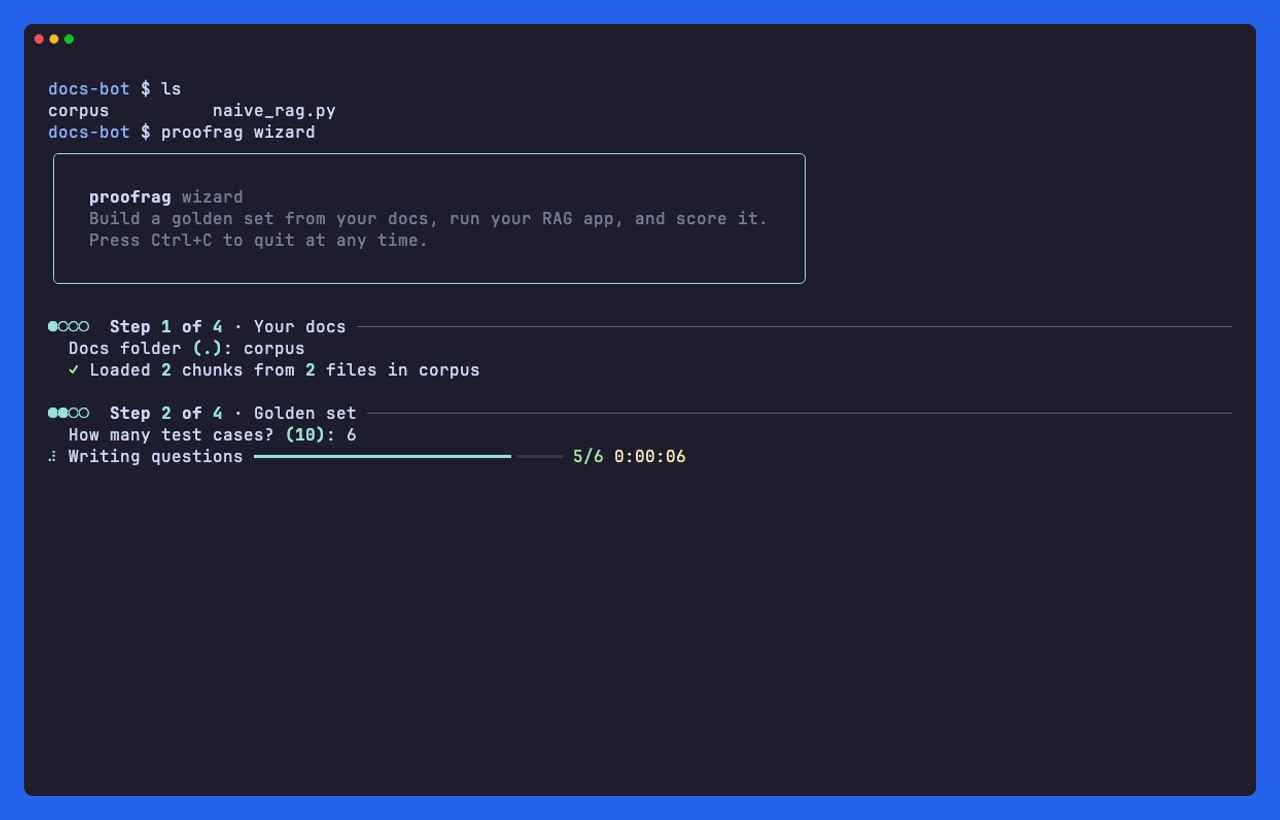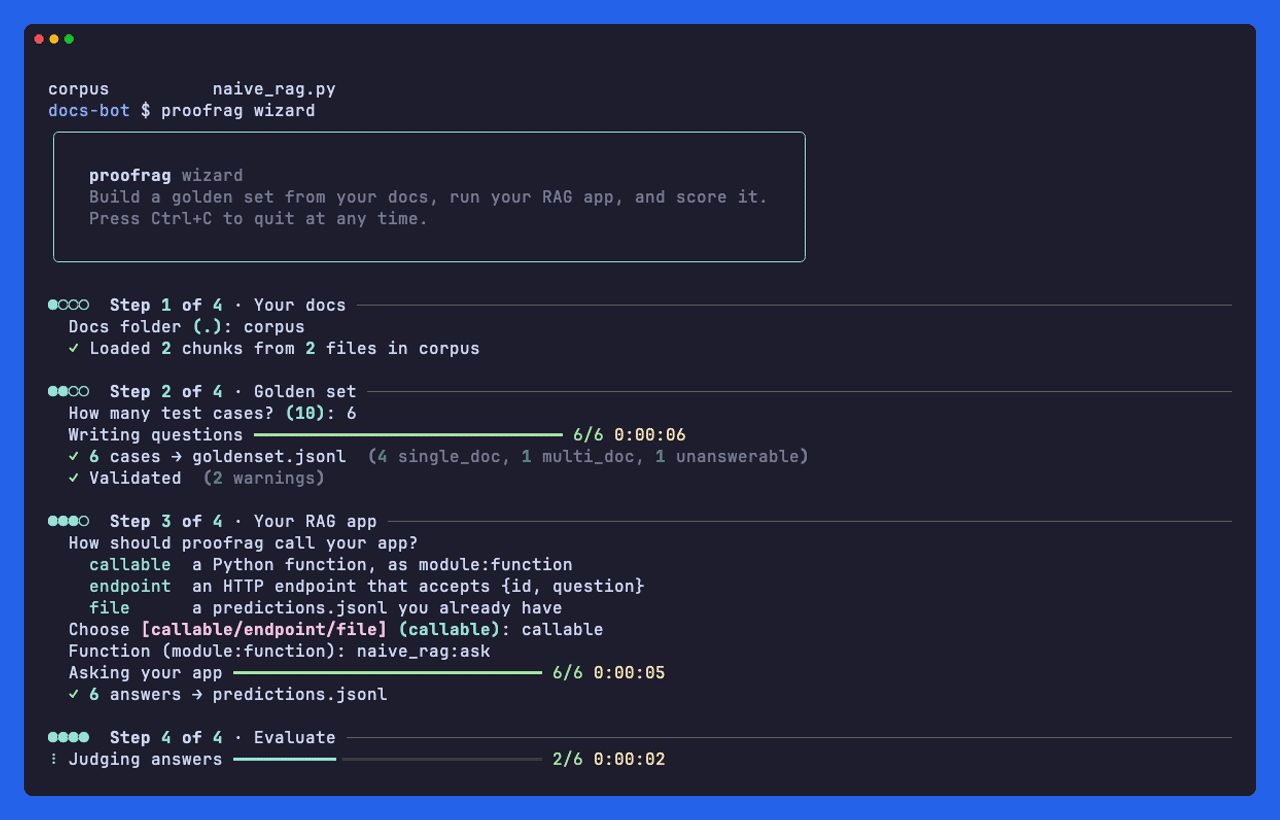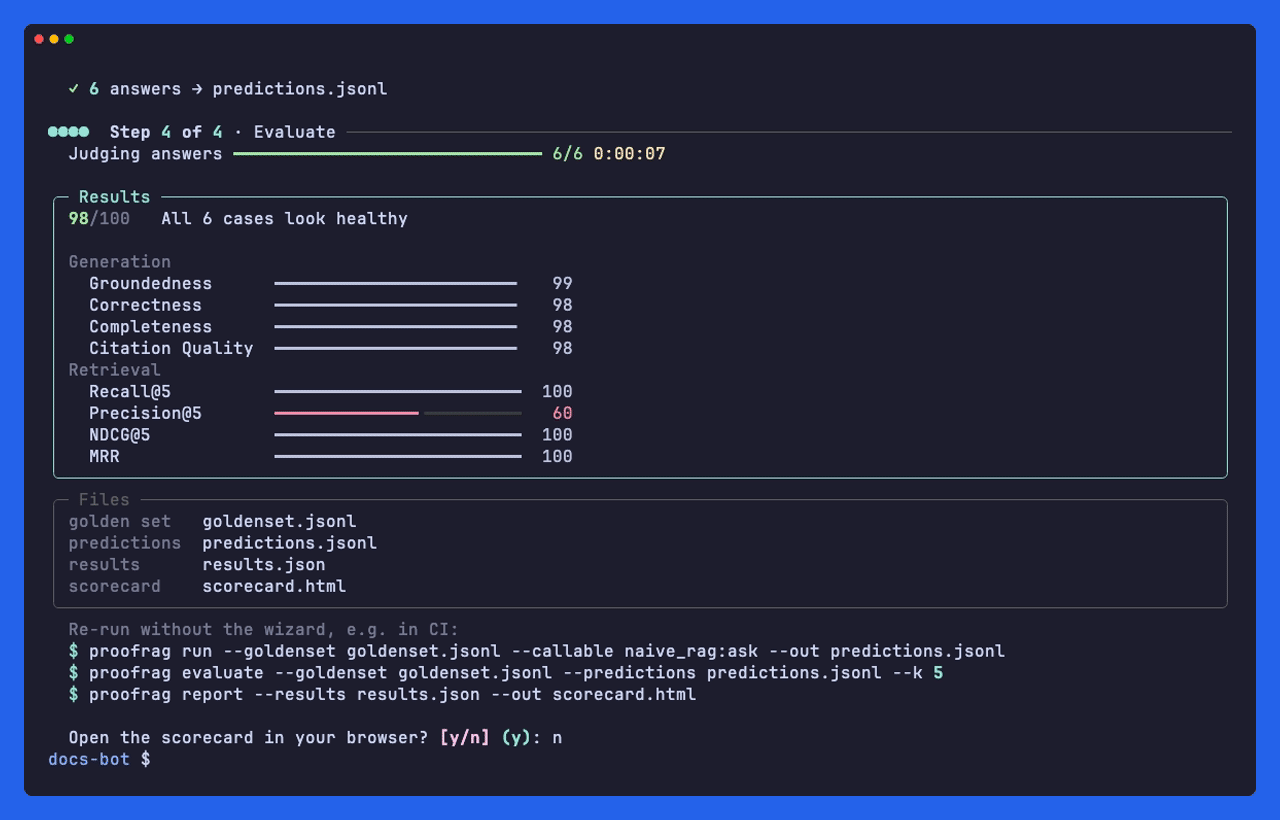
Or walk through your own project with the guided wizard:
pipx install "proofrag[anthropic,tui]"
proofrag wizard
Use [openai] for OpenAI, or for a local, OpenAI-compatible server such as Ollama.
In Claude Code, run /plugin marketplace add unshDee/proofrag, then
/plugin install proofrag@proofrag, and ask it to "evaluate my RAG".
proofrag generate --corpus ./docs --out goldenset.jsonl --n 20        # golden set from your docs
proofrag validate --goldenset goldenset.jsonl --corpus ./docs         # review before committing
proofrag run --goldenset goldenset.jsonl --callable myapp.rag:answer --out predictions.jsonl
proofrag evaluate --goldenset goldenset.jsonl --predictions predictions.jsonl --out results.json
proofrag report --results results.json --out scorecard.html
Gate it in CI with the GitHub Action:
- uses: unshDee/proofrag@v0.10.0
  env:
    ANTHROPIC_API_KEY: ${{ secrets.ANTHROPIC_API_KEY }}
  with:
    goldenset: eval/goldenset.jsonl
    predictions: predictions.jsonl
baseline: eval/baseline.json # fail if any metric regresses- Golden sets grounded in your docs. Single-document, multi-document and unanswerable cases, validated before they become a baseline.
- Retrieval and generation are scored separately. Recall@k, NDCG@k and MRR show whether the evidence arrived. Answer metrics show what the model did with it.
- Reproducible runs. Every run records the judge, prompt version, matcher and
dataset fingerprint, and
diffrefuses to compare mismatched runs. - Blind A/B. Compare two variants on the same cases, with answer order randomized.
- Portable. Self-contained HTML reports. Anthropic, OpenAI or local models, or score with DeepEval, Ragas or Jev.
| The evaluation loop | Corpus loading, validation, prediction adapters, metrics |
| CI gates | Score floors, baseline diffs, the GitHub Action |
| A/B and case studies | Blind comparisons and three reproducible studies |
| Judges and providers | Providers, env vars, DeepEval, Ragas, Jev |
| Agent Skill | Use proofrag from Claude Code, Codex and other agents |
| Upgrading | Baseline changes between versions |
Issues and PRs are welcome; see CONTRIBUTING.md. Security notes are in SECURITY.md. MIT licensed.